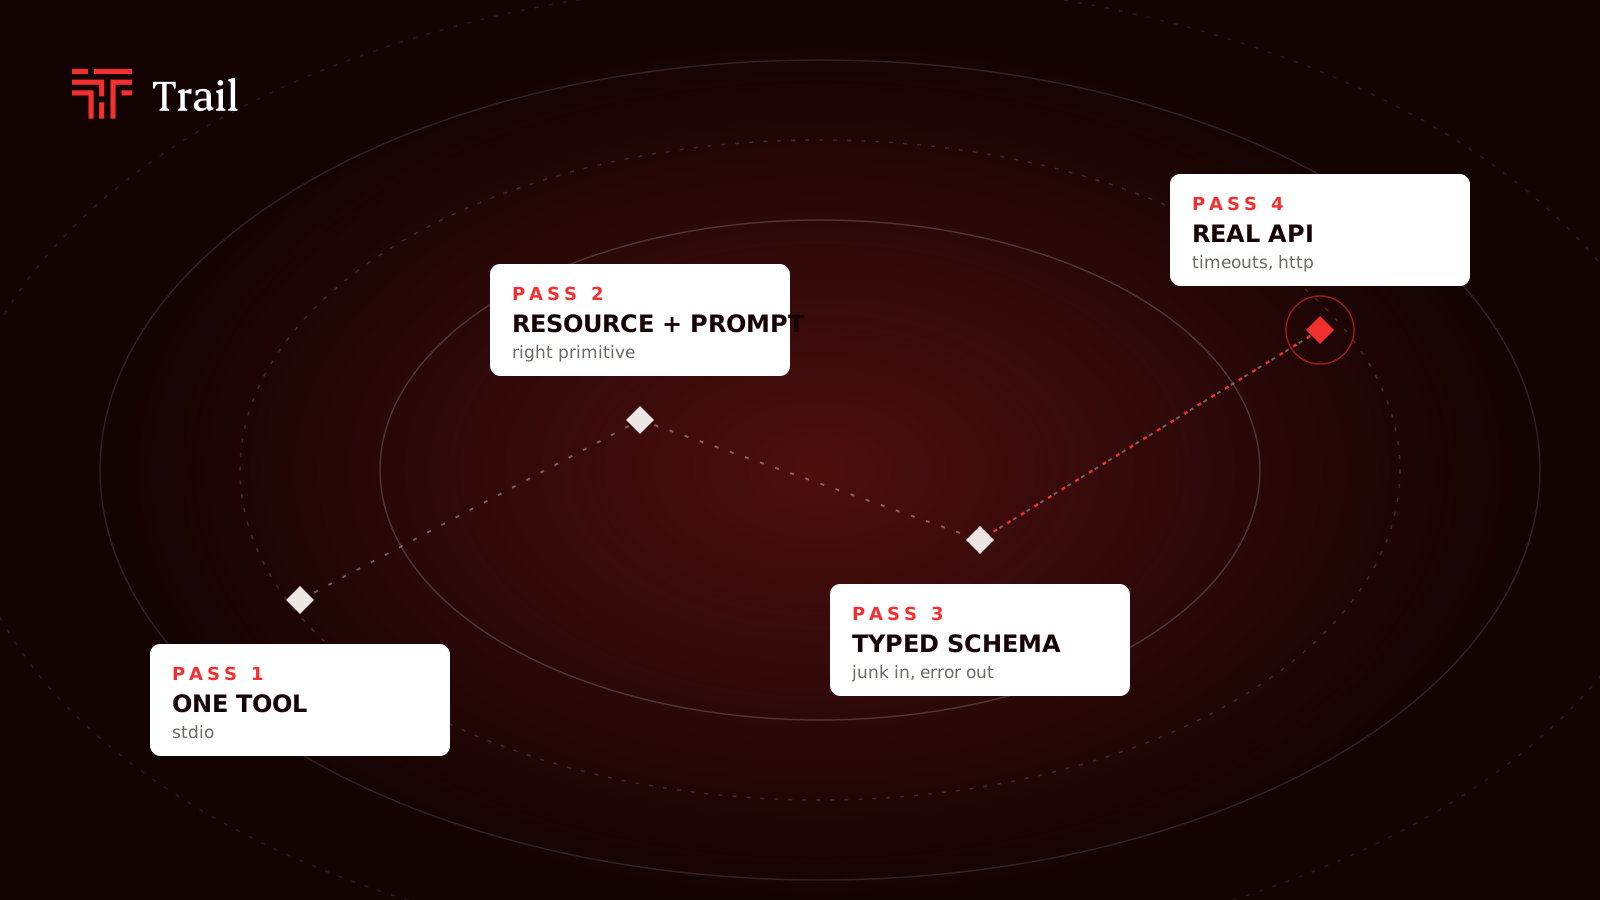
Build an MCP Server in Four Passes
A working MCP server in fifteen lines, then three more passes that each hit a real edge of the protocol: stdout as the wire, the wrong primitive, junk arguments, and a slow upstream.
Blog
A working MCP server in fifteen lines, then three more passes that each hit a real edge of the protocol: stdout as the wire, the wrong primitive, junk arguments, and a slow upstream.
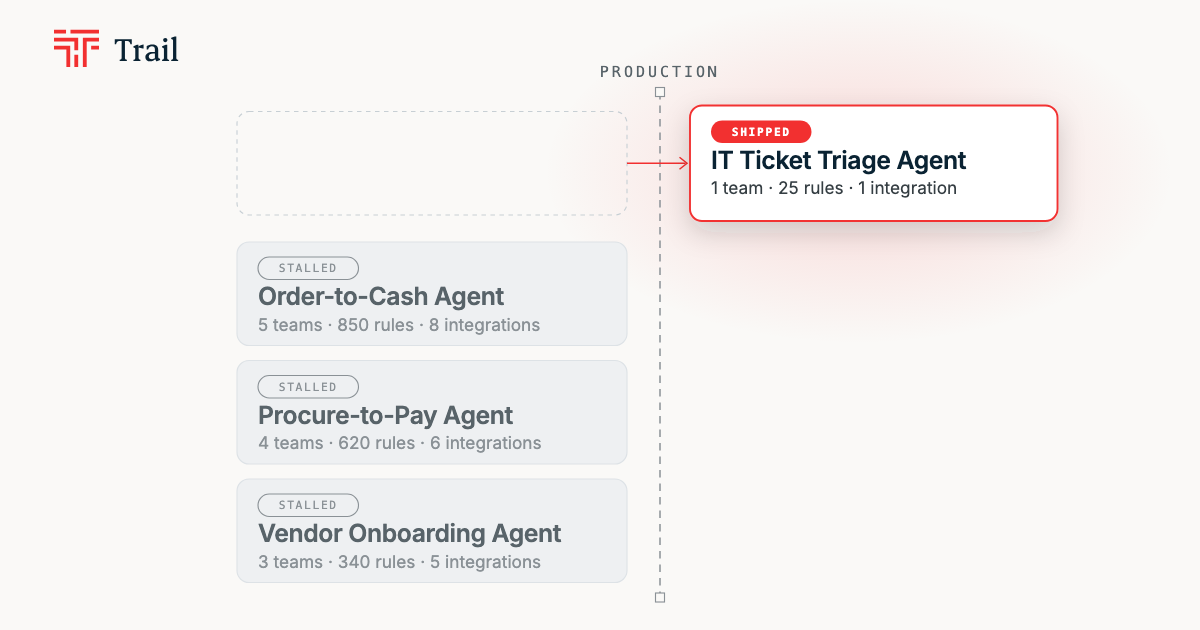
That payoff came from a simple task inside one team. Complex work pulls rules from more systems and teams, and those rules often conflict. Better retrieval won't help. It finds every rule that applies but can't tell an agent which one wins.
 Oct 6, 2026
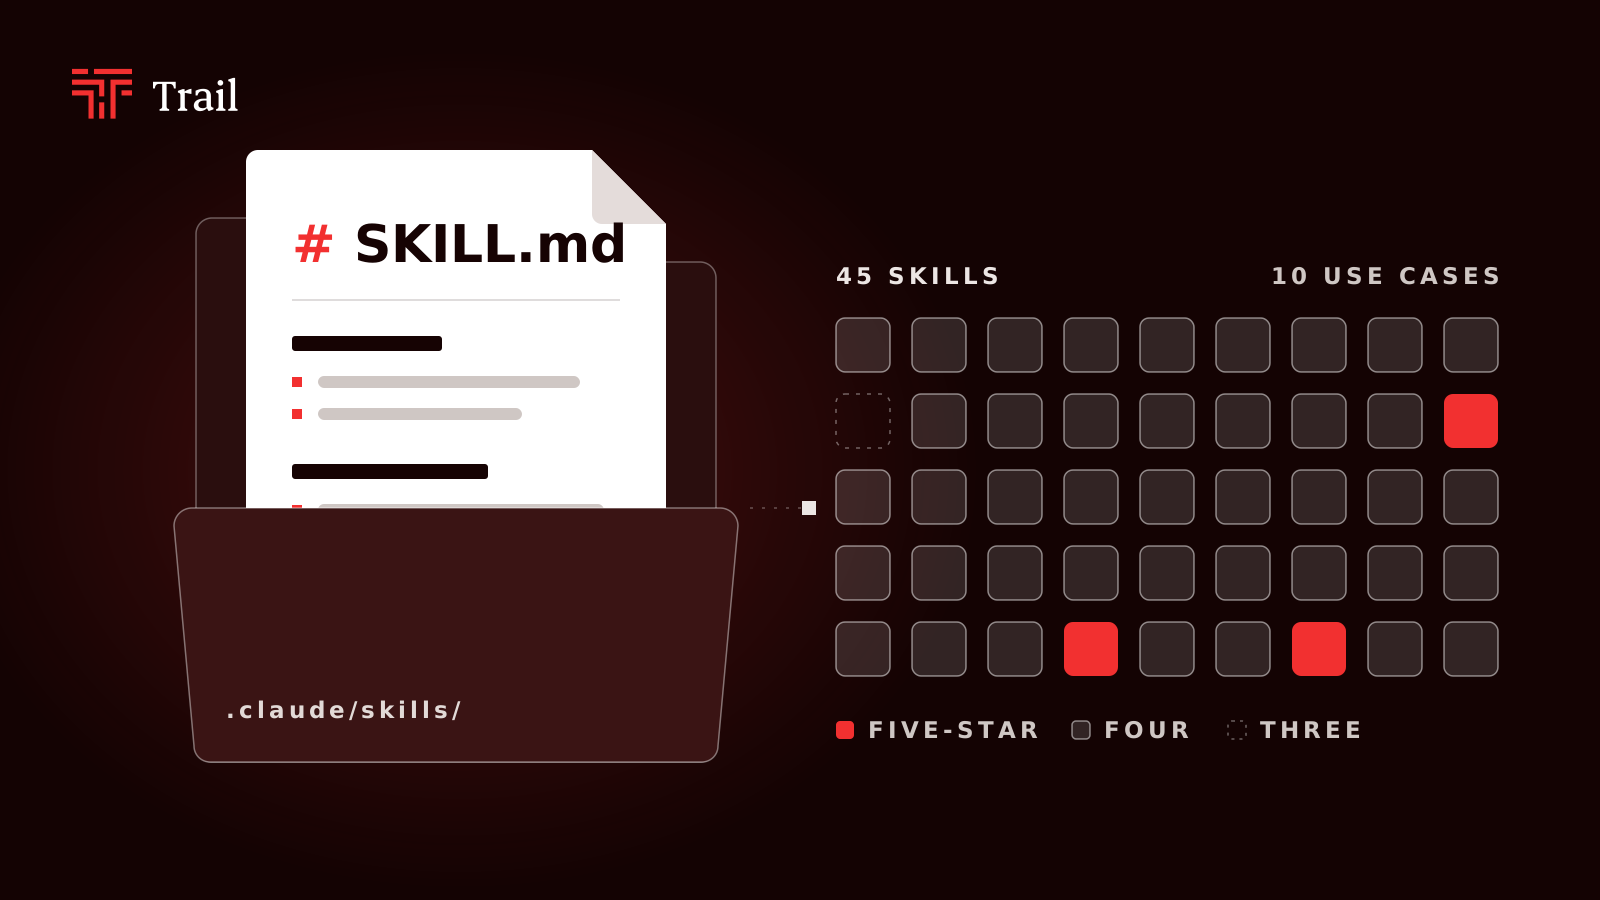
45 Claude Code skills graded by evidence across 10 use cases.
AGENTS.md tells AI coding agents how to build and test your project. How to create one, what belongs in it, and what five studies say about whether it works.
Graphify, Codegraph, and Graft all map your repo for coding agents. What each one's benchmarks actually prove, and which to pick for multi-file changes.
A context graph stores entities, rules, and decision traces for AI agents. How to create one in seven steps, what a decision trace records, and how agents use it.
Agents break SOPs in seven distinct ways. The evidence on each, where to put rules in Claude and ChatGPT, and how to test that a rule actually holds.
CLAUDE.md gives Claude Code persistent instructions for a project. What 8 published studies measured about compliance, token cost, and what to delete.
A company brain is a maintained knowledge layer people and agents both read. What goes in, how to build one in seven steps, what it costs, and why most fail.
An MCP server exposes tools to AI applications through the Model Context Protocol. How they work, when to build one, and how to build, vet, and connect one.
We explain why AI agents need to capture decisions, how context graphs achieve this, and how AI agents can use these graphs.
All 25 announcements from Orlando, what's actually shipping vs. what's marketing — and what it means for the document and data foundation of the autonomous enterprise.
See how the Claude legal plugin helps in-house legal teams with contract review, compliance scanning, due diligence, obligations tracking, and drafting.
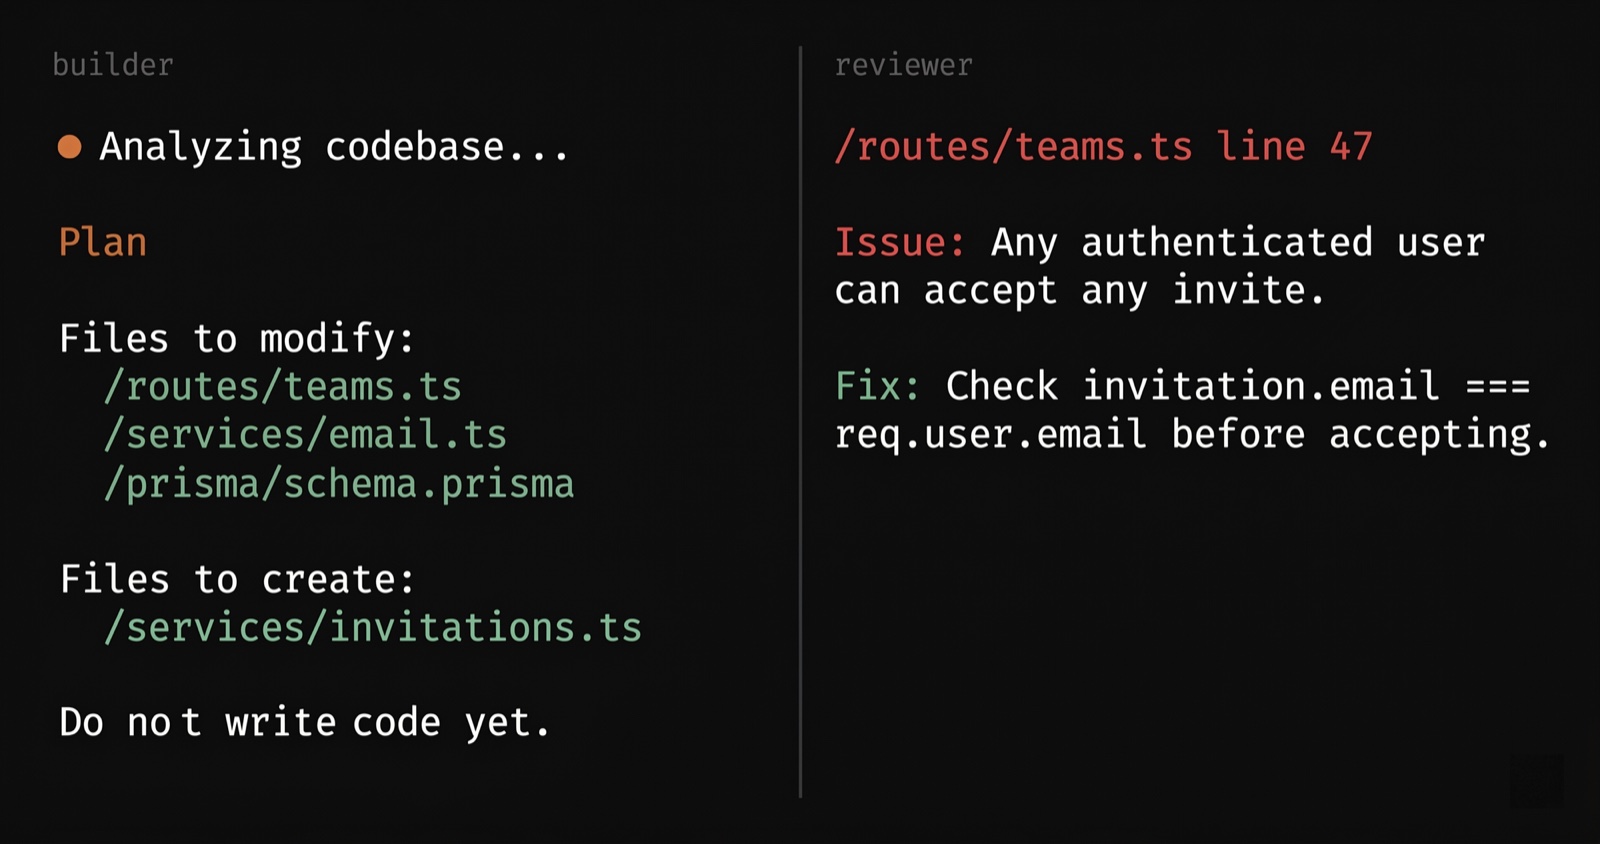
Learn 5 practical vibe coding best practices for Claude Code and coding agents: CLAUDE.md, planning, review agents, safer prompts, and diff review.
Learn what MMLU, GPQA Diamond, SWE-bench, HealthBench, and Chatbot Arena actually measure, and how labs game benchmark scores.
Learn what AI tokens are, why Claude hits limits fast, and how to cut waste from context windows, history, files, tools, and reasoning.
See how finance teams use Claude for one-pagers, CIMs, comps, DCF models, reconciliations, and variance commentary, plus key human checks.
Yes, OpenAI and Google degrade their models. OpenAI admitted silent updates after denying it. Gemini redirects models. With full evidence.
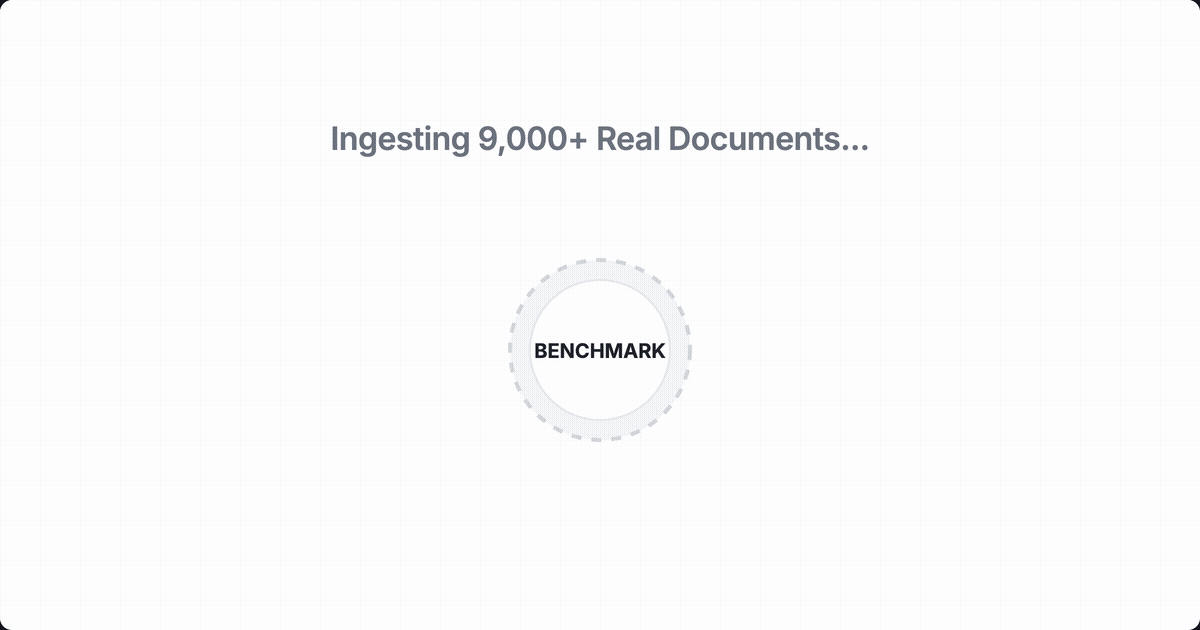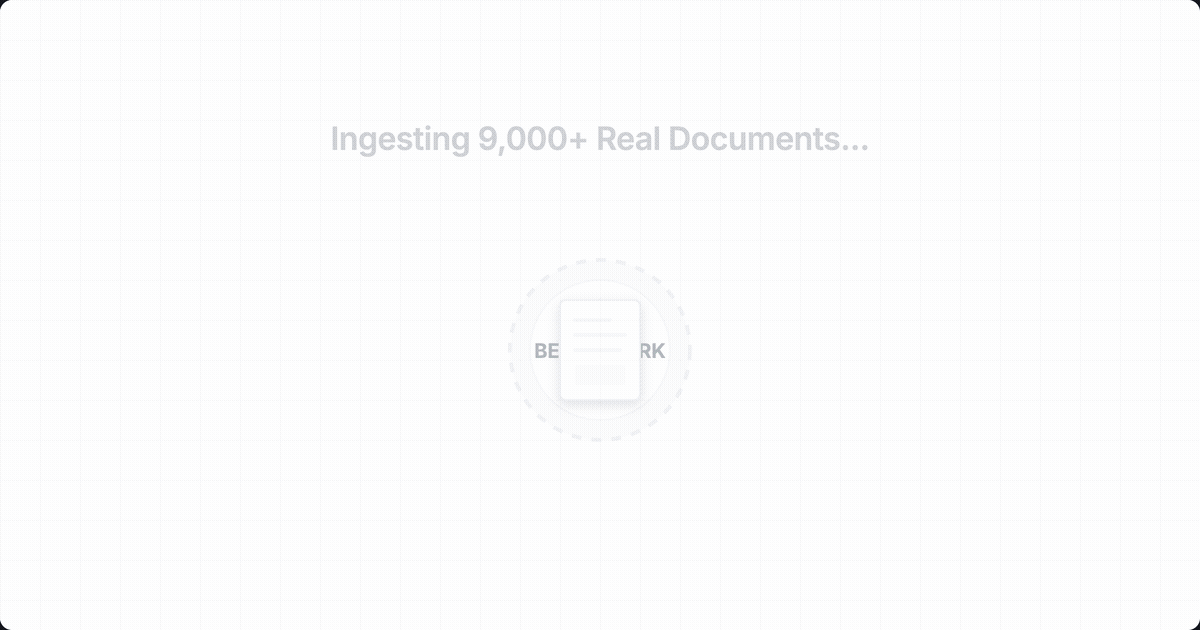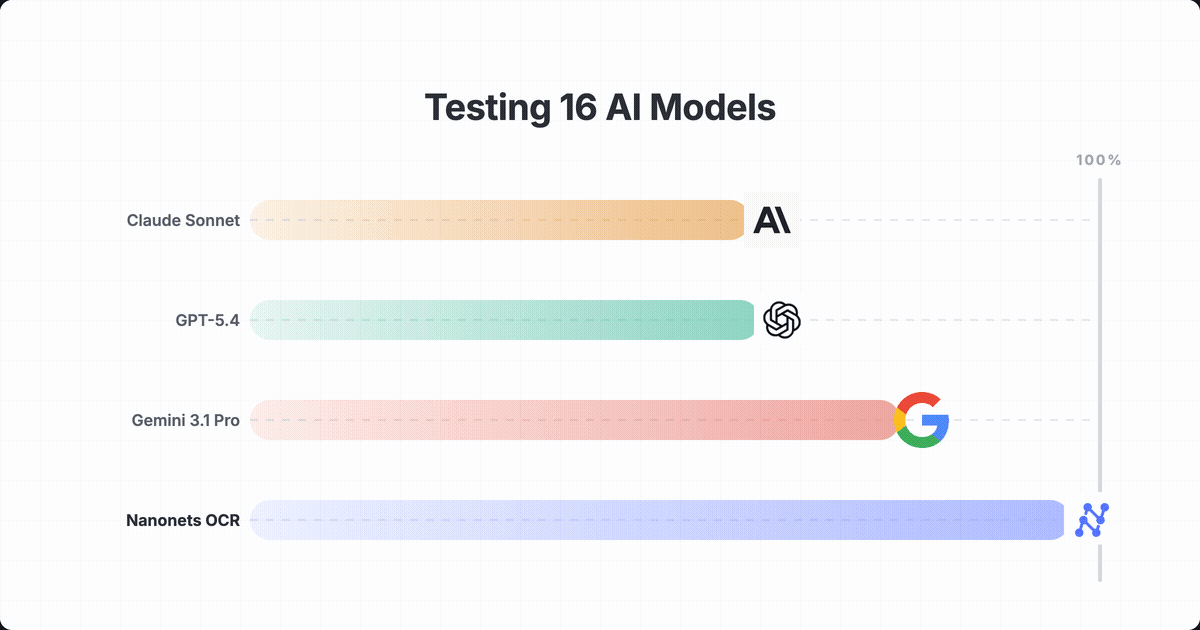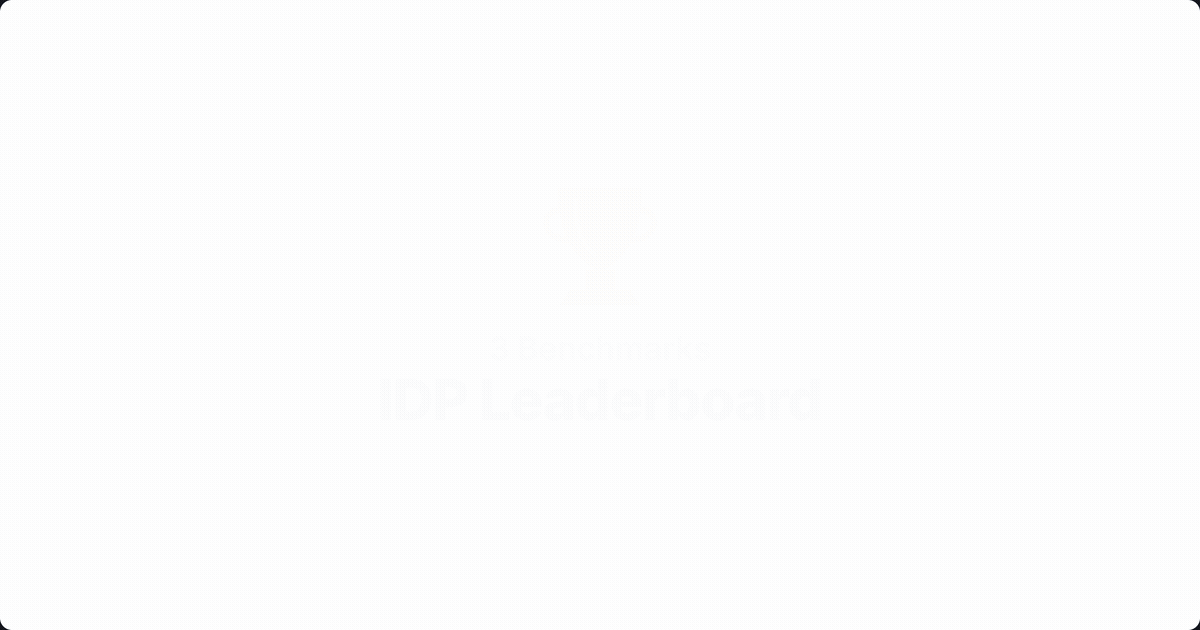
We benchmarked GPT-5.4, Gemini 3.1 Pro, Claude Opus, Sonnet, and 12 others on 3 Open OCR Benchmarks
Claude AI was used in the Venezuela raid that captured Maduro. Anthropic didn't know how until they asked Palantir. All possible scenarios here.
Point Trail at the policy, SOP, agreement that decides your work, and watch it build an agent using rules traced back to the text they came from.